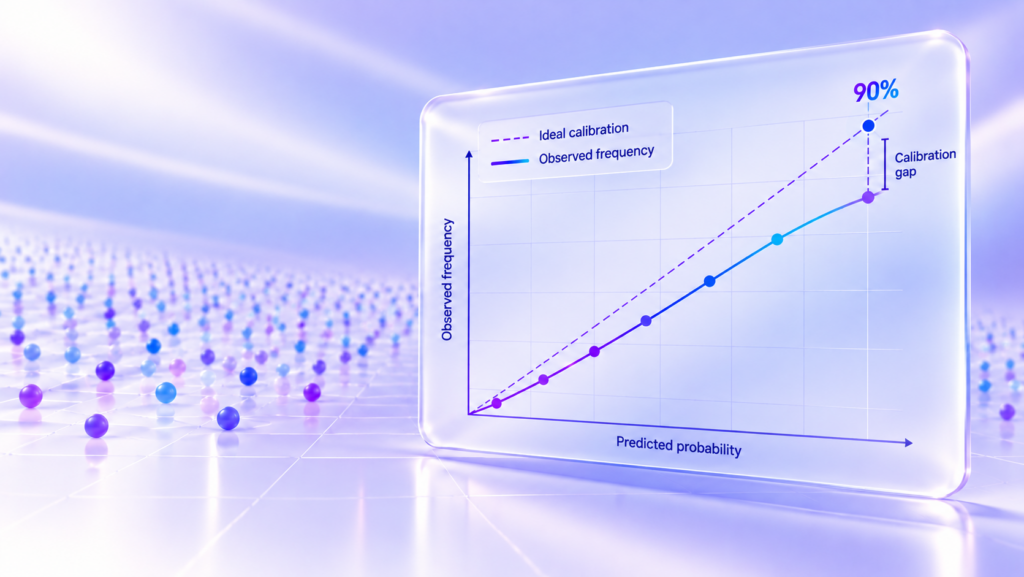
When a predictive model assigns a customer a 90% churn score, a CRM team may reasonably consider that account a priority for retention activities, particularly if the potential loss would have significant financial consequences. Before committing resources, however, the organization needs to understand whether that percentage represents a reliable estimate of the customer’s likelihood of leaving or simply reflects the model’s ability to identify accounts with comparatively higher risk.
The distinction is important because a model can perform exceptionally well at ranking customers according to their likelihood of churn while producing probability estimates that do not accurately reflect how frequently the event occurs. In practice, a system might consistently identify the customers most likely to leave while systematically overstating their absolute risk, creating a misleading picture when those percentages are used to estimate future losses or determine how much money should be invested in retention.
For organizations increasingly relying on predictive intelligence to guide commercial decisions, probability calibration in machine learning provides a way to evaluate whether predicted probabilities correspond to observed outcomes, helping distinguish models that are effective at prioritization from those whose numerical estimates can also support financial and operational decisions.
What Does a 90% Churn Score Actually Mean?
The interpretation of a predictive score depends on what the model was designed to produce and how its output has been validated, since values expressed on a scale from zero to one are not necessarily reliable probabilities simply because they can be displayed as percentages.
Some predictive systems generate scores primarily intended to rank observations according to relative risk, while others estimate the probability of a defined event occurring within a specified period. Although these outputs can appear similar in a CRM interface, they provide different types of information and should not automatically be used interchangeably.
Consider a company that can contact only 500 customers during an upcoming retention campaign. If its objective is to identify the accounts most likely to leave, a model with strong ranking performance can provide useful guidance even when the precise numerical values of its scores are imperfect, because the operational decision depends mainly on which customers appear riskier relative to others.
The requirements change when the same organization uses predicted churn percentages to calculate expected customer losses, estimate the financial return of retention initiatives or establish a threshold above which an intervention becomes mandatory. In these situations, systematically overstated probabilities could lead to unnecessary spending, while underestimated risks could cause the business to overlook customers whose potential departure carries substantial economic consequences.
A well-calibrated model assigning probabilities close to 90% to a sufficiently large group of customers should observe churn in approximately nine out of ten cases, assuming that the evaluation population and prediction conditions are representative. This does not mean that the future of any individual customer can be known with certainty, but rather that the estimated probabilities should correspond to the frequency of the event across comparable predictions.
The prediction horizon introduces another important consideration, since a 90% probability of churn over the next 30 days describes a fundamentally different level of urgency from the same probability calculated over the following 12 months. Understanding the predicted event, the relevant period and the reliability of the numerical estimate is therefore essential before translating an apparently precise percentage into a business decision.
Why Accurate Customer Rankings Do Not Guarantee Reliable Probabilities
Machine learning models can be evaluated through several performance dimensions, but the distinction between discrimination and calibration becomes particularly important when predicted probabilities influence operational or financial decisions.
Discrimination describes how effectively a model distinguishes observations that experience an event from those that do not, meaning that a churn model with strong discriminatory performance generally assigns higher scores to customers who eventually leave than to those who remain. Calibration, by contrast, examines whether the numerical probabilities assigned to those customers correspond to the event frequencies subsequently observed.
A model may successfully place customers in the correct order of risk while assigning probabilities that are consistently too high or too low, just as a model that assigns every customer a probability close to the overall churn rate may appear reasonably calibrated at an aggregate level without providing meaningful information about which individual accounts deserve attention.
These differences explain why strong ranking performance cannot be treated as evidence that the model’s percentages accurately represent customer risk, particularly when decision-makers intend to use those figures to estimate losses or compare interventions with different costs.
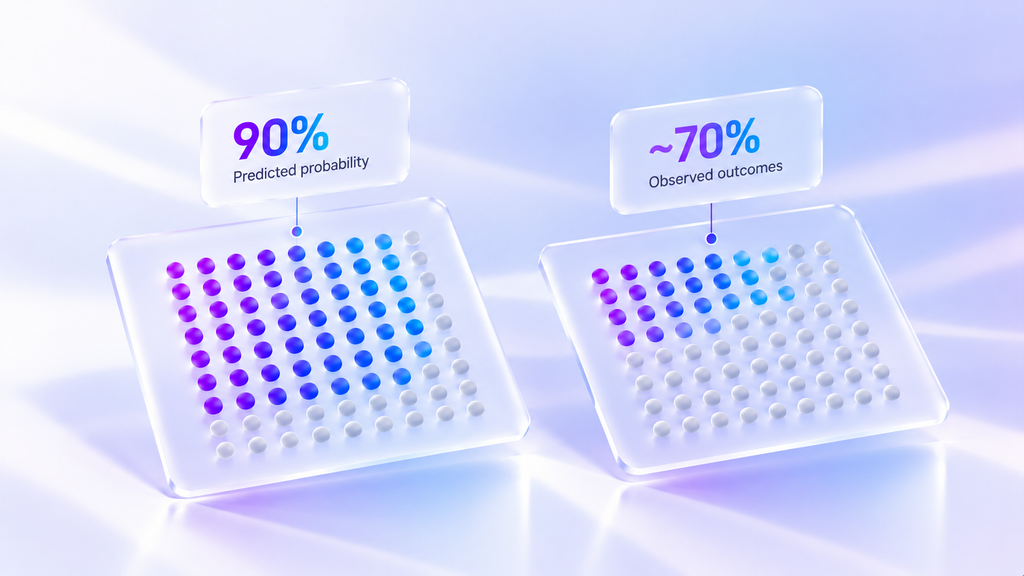
One way to evaluate calibration is through reliability diagrams, which group predictions into probability ranges and compare their average predicted values with the proportion of observed events. If customers receiving churn estimates close to 70% actually leave at approximately that frequency, the model demonstrates reasonable calibration within that range, whereas substantial differences between expected and observed outcomes may indicate that the estimates require further investigation.
Other evaluation metrics, including the Brier score and log-loss, provide complementary information about the overall quality of probabilistic predictions, although they should not be interpreted as measures of calibration alone. As explained in the scikit-learn documentation on probability calibration, probabilistic scoring rules reflect multiple aspects of predictive quality, including how effectively the model distinguishes outcomes and the uncertainty inherent in the prediction problem.
Consequently, an improvement in log-loss does not necessarily establish that calibration has improved, while a strong discrimination metric cannot confirm that predicted percentages are numerically reliable. Organizations using these models for business decisions need to evaluate both properties in relation to the intended application, rather than relying on a single performance indicator.
What Recent Research Reveals About Recalibration
A study published in September 2026 in the Proceedings of Machine Learning Research challenges the assumption that applying an established recalibration technique will necessarily make a predictive model’s probability estimates more reliable.
In When Post-Hoc Calibration Hurts: Platt Scaling and Isotonic Regression on Modern Tabular Models, researchers Valery Manokhin and Daniel Grønhaug examined 21 classifiers across 30 binary classification tasks, conducting 3,150 evaluations for each calibration method to assess how post-processing approaches affected probabilistic predictive performance.
Their findings show that two widely used methods, Platt scaling and isotonic regression, did not consistently improve the results of the original models. When evaluated through log-loss, isotonic regression produced improvements in 43.7% of cases, while Platt scaling improved performance in 49.8%, indicating that neither approach could be assumed to deliver a benefit across the experimental conditions considered.
The comparison with discrimination metrics makes the findings particularly relevant to organizations relying on predictive models for customer or risk management. Across the experiments, average changes in AUC-ROC remained below 1%, even when probabilistic scoring performance changed more substantially, demonstrating how a model’s apparent ranking quality can remain relatively stable while other properties of its probability predictions deteriorate or improve.
For a company evaluating model quality primarily through ranking metrics, these differences can be difficult to detect, especially when the predictive output is subsequently presented to commercial teams as a percentage that appears sufficiently precise to guide spending decisions.
The results do not suggest that recalibration is unnecessary or that particular methods should be avoided in every application. Instead, they demonstrate why recalibration should be treated as a procedure requiring independent evaluation, with its effectiveness assessed against appropriate probabilistic metrics and representative validation data.
It is also important to distinguish the overall quality of probability predictions from calibration itself, since the study’s log-loss results cannot be interpreted as direct measurements of calibration in isolation. Nevertheless, the research provides strong evidence that improvements in ranking performance and probabilistic performance do not necessarily follow the same pattern, reinforcing the need for evaluation methods that reflect how the predictions will actually be used.
Why Calibration Matters for CRM and Risk Decisions
The commercial importance of calibration becomes clearer when comparing decisions based on relative customer priority with those that depend on the numerical magnitude of predicted risk.
A CRM team working with a fixed outreach capacity may primarily need a reliable ranking of customers, allowing sales or retention specialists to focus on the accounts most likely to leave. Another organization may use predicted probabilities to estimate future customer losses, allocate budgets across different retention initiatives or determine whether the expected financial benefit of an intervention justifies its cost.
In the second situation, miscalibrated probabilities can distort economic assumptions even when the model identifies high-risk customers correctly, because the business may overestimate the expected number of departures or underestimate the resources required to manage a particular level of risk.
Similar considerations arise in credit risk, insurance and other applications where predicted probabilities influence expected loss calculations, financial exposure or operational thresholds. In each case, the numerical reliability of the estimate becomes an important component of the decision, alongside the model’s ability to distinguish between different levels of risk.
Calibration alone, however, cannot determine whether a particular intervention should take place, since a reliable estimate of an event’s probability does not establish how that probability would change if the organization took action.
A customer with a well-calibrated 90% probability of churn, for example, may still be unlikely to respond to a promotional offer, making the effectiveness of that intervention a separate question requiring causal or experimental evidence. Even when a retention initiative can reduce the probability of departure, its expected economic contribution depends on factors such as incentive costs, customer value and the resources needed to deliver the intervention.
For marketing and CRM leaders, reliable probability estimates are therefore one component of a broader decision process in which predicted risk, expected intervention effects and commercial consequences must be evaluated together.
Keeping Probability Estimates Reliable Over Time
Even when a model produces well-calibrated probabilities during development, its numerical reliability may change after deployment as customer behavior, market conditions and underlying event frequencies evolve.
A churn model trained on historical purchasing patterns may begin to overestimate risk if customer retention improves across the business, or underestimate it when market conditions increase the likelihood of customers leaving. These changes can affect the relationship between predicted probabilities and observed outcomes without necessarily producing an equivalent deterioration in the model’s ability to rank customers.
Organizations using probability-based decision rules consequently need to compare predicted risks with actual outcomes over time, examining whether calibration remains appropriate for the population and prediction horizon in which the model operates.
Performance should also be evaluated across relevant customer segments, since a model that appears reasonably calibrated across the overall customer base may produce less reliable estimates for particular groups whose characteristics or behavior differ from the average.
When meaningful deterioration becomes apparent, teams may need to investigate changes in data distributions, review the underlying predictive model or test whether a recalibration procedure improves probabilistic performance. Such adjustments require appropriate validation, with information used to fit calibration methods kept separate from data reserved for final evaluation and with temporal relationships respected when predictions concern future events.
For organizations adopting predictive AI, the broader implication is that a model’s numerical output should be evaluated according to the decision it is intended to support, whether that decision involves prioritizing customers, estimating financial exposure or determining when additional resources should be committed.
A reliable ranking may be sufficient when the objective is to select the highest-risk accounts, whereas decisions that depend on absolute risk levels require stronger evidence that predicted probabilities accurately reflect the frequency of the underlying event.
The business value of a predictive probability ultimately depends on understanding what the number represents, whether its numerical meaning remains reliable and how that information contributes to better decisions.