
A synthetic customer dataset can closely resemble real data yet perform poorly when used to train a predictive model. Purchase frequencies may look plausible and customer profiles may follow familiar distributions, while the relationships needed to predict churn, conversion, or purchasing behavior have been weakened during generation.
This distinction matters when organizations use synthetic data to supplement limited observations or represent rare outcomes. More training records are not necessarily more useful records.
Research presented at ICML 2026, ReTabSyn: Realistic Tabular Data Synthesis via Reinforcement Learning, examines how generation can prioritize relationships relevant to downstream prediction. Its central implication is practical: synthetic data should be evaluated for the task it must support, not just for its resemblance to real data.
What Is Synthetic Data for Machine Learning?
Synthetic data consists of artificially generated observations designed to reproduce selected properties of real datasets or an underlying data-generating process.
In tabular machine learning, records may contain customer attributes, transaction histories, engagement measures, and target outcomes. Generators learn patterns from existing observations and produce additional records, which can support experimentation or augment limited training data.
Two qualities must be distinguished:
- Statistical fidelity: Similarity to the original data in distributions, correlations, and dependencies.
- Predictive utility: The ability to train models that perform well on independent, real-world observations.
High fidelity does not guarantee high utility. Consider a dataset containing purchase frequency, spending, and subscription cancellations. A generator might reproduce the overall cancellation rate while weakening the relationship between declining purchasing activity and subsequent churn.
For churn prediction, that lost relationship may matter more than the similarity of individual variable distributions.
In statistical terms, the challenge concerns the joint distribution of features and outcomes, P(X, y), and especially the conditional relationship P(y | X). Preserving the signals required for prediction is essential; reproducing realistic-looking records is not enough.
How ReTabSyn Addresses Predictive Utility
In ReTabSyn: Realistic Tabular Data Synthesis via Reinforcement Learning, Xiaofeng Lin and colleagues investigate how to align synthetic data generation more closely with predictive performance.
Their method fine-tunes a language-model-based tabular generator using Direct Preference Optimization (DPO). Preferred and less desirable training examples are constructed by modifying target values or correlated features, providing a learning signal about relationships the generator should preserve.
This approach seeks to protect feature–target relationships while retaining important dependencies between input variables. It does not require human preference labels or an external classifier to assign rewards.
The distinction is important: rather than optimizing solely for a plausible reproduction of source records, the training objective gives greater weight to relationships that matter for a downstream label. That design choice still requires empirical testing; it is not a guarantee that every useful dependency will survive generation.
What the Experiments Show
The study evaluates ten tabular classification benchmarks, including datasets related to customer churn and online shopping. Experiments examine three demanding conditions: small training datasets, class imbalance, and distribution shift.
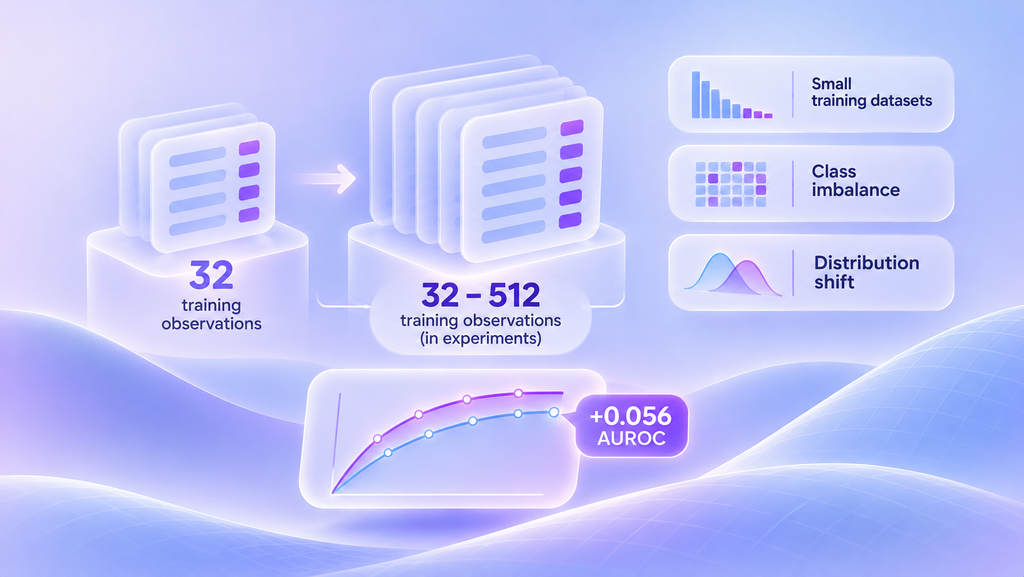
For small-data experiments, training subsets contain 32–512 observations. ReTabSyn is compared with methods including SMOTE, TVAE, TabSyn, and GReaT.
When classifiers were trained exclusively on synthetic data, ReTabSyn reported stronger average predictive results than the evaluated synthetic baselines across the small-data settings.
With 32 training observations, its average AUROC exceeded the SMOTE baseline by 0.056 points in the synthetic-only benchmark configuration. That advantage narrowed as more real observations became available.
AUROC measures discrimination across classification thresholds; a difference of 0.056 is not a 5.6% increase in business results or a guaranteed gain on new datasets. Its significance depends on the experimental comparison and the intended application.
Results for rare classes and distribution shift were also favorable relative to the tested baselines. However, these findings concern specific classification benchmarks. They do not establish comparable gains for every enterprise dataset, regression task, or commercial deployment.
Three Conditions That Require Special Attention
The research is relevant to common enterprise data limitations, but each requires a different validation strategy.
Limited historical observations. Synthetic augmentation can add records when training data is scarce. It may also reproduce noise or unstable patterns learned from a small sample. The test is whether augmentation improves performance on held-out real data.
Rare outcomes. Churn, fraud, or uncommon conversions can leave few positive examples. Overall accuracy may conceal poor minority-class detection; precision-recall AUC and other class-sensitive measures can provide a more informative evaluation.
Distribution shift. A model trained on one population may underperform on another. ReTabSyn tests particular differences between training and evaluation subgroups, not every form of change in customer behavior over time.
Synthetic data generation should therefore be assessed under conditions that resemble the model’s intended operating environment.
How Should Organizations Evaluate Synthetic Data Quality?
A useful evaluation goes beyond visual resemblance or summary statistics. It asks whether synthetic records improve the intended task without introducing unacceptable risks.
| Evaluation dimension | What to examine |
| Statistical fidelity | Distributions, correlations, and meaningful dependencies |
| Predictive utility | Model performance on independent real observations |
| Rare-event performance | Minority-class detection using suitable metrics |
| Generalization | Results across relevant populations and distribution changes |
| Privacy and validity | Disclosure risk, implausible records, domain constraints, and compliance requirements |
An evaluation can compare models trained on real data alone, synthetic data alone, and real data augmented with synthetic records. Use consistent preprocessing, model selection, metrics, and test sets to make results comparable.
The evaluation metric should match the business question. Ranking quality may matter for outreach prioritization, while calibration matters when predicted probabilities drive thresholds or resource allocation. Gains in a single aggregate score can also conceal deterioration in an important customer segment.
Keep final evaluation data separate from generator development and model tuning. For time-dependent outcomes, apply temporal validation: information recorded after a cancellation or purchase must not be available to a model predicting that earlier event.
Privacy must be assessed independently. Synthetic records are not automatically anonymous; generators may reproduce sensitive or identifiable patterns, particularly from rare observations.
ReTabSyn reports empirical privacy-risk experiments but offers no formal privacy or fairness guarantee. The authors also acknowledge limitations concerning regression, target-specific optimization, and computational requirements.
A broader 2026 survey in Transactions on Machine Learning Research similarly treats utility, fidelity, domain alignment, privacy, and diversity as distinct evaluation dimensions. No single metric establishes that a synthetic dataset is fit for every purpose.
What This Means for Predictive Customer Intelligence
Consider a business developing churn predictions from purchasing activity, account characteristics, service interactions, and cancellation history. The dataset may contain relatively few customers who have actually canceled.
Synthetic augmentation could increase the number of training examples, but the relevant question is whether it improves predictions on real customers, particularly among segments where retention action is being considered.
Even a measurable gain in predictive performance does not automatically translate into improved retention. A high churn score identifies risk; it does not prove that contacting a customer will prevent departure. Commercial impact also depends on customer value, intervention cost, and effectiveness.
This separation between model quality and intervention effectiveness is particularly important when rare events are expensive to act upon. More accurate scores can help identify where to investigate, but decisions still require costs, constraints, and evidence about which actions work.
The same distinction applies to purchase propensity and response prediction. Synthetic data should be judged in the context of both the predictive task and the decision the model is intended to inform.
From Realistic Data to Reliable Predictions
Synthetic data can help organizations investigate predictive problems when examples are scarce, target classes are imbalanced, or access to original records is constrained. But synthetic realism and predictive usefulness are not interchangeable.
ReTabSyn offers evidence that prioritizing prediction-relevant relationships can improve downstream classification performance in challenging benchmark conditions. It does not eliminate the need for careful validation, privacy assessment, or testing under operational constraints.
The practical standard is straightforward: synthetic data earns its place in a machine learning workflow only when it preserves meaningful predictive signals and supports reliable performance on real observations.